Innhold Show
Kimi K3.1 Pro now has open weights. Moonshot promised to release them by November 4, and the model files are indeed available on Hugging Face.
That is an important difference from merely being able to select the model in Kimi, Kimi Code or an API. Independent developers and providers can now download the weights, inspect the model, adapt it and run it on their own infrastructure. Moonshot has not simply pasted an “open” label onto an API service.
This is good. Really good. Just do not read “open weights” as “download it to your gaming PC tonight.” Kimi K3.1 Pro has 2.8 trillion parameters, activates 104 billion of them per token, and its Hugging Face repository is about 1.56 TB. The weights are open. The hardware requirements are still rather brutal.
What do the Kimi K3.1 Pro open weights include?
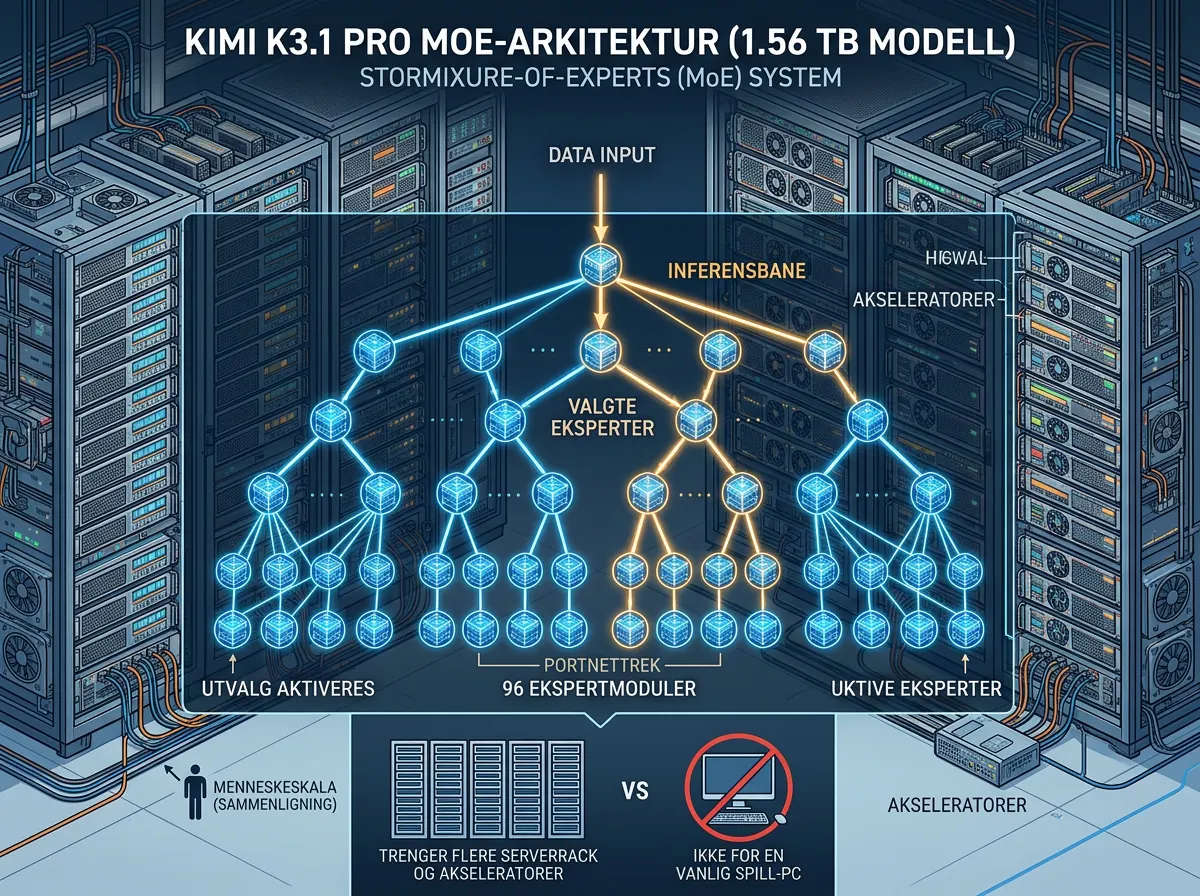
Moonshot has published the complete Kimi K3.1 Pro model on its official Hugging Face account. The repository contains the configuration, tokenizer, processing code, license and 96 weight files. It describes a multimodal Mixture-of-Experts model with 2.8 trillion total parameters, 104 billion active parameters and a 1,048,576-token context window.
K3.1 Pro was post-trained from Kimi K3 and is the first model in the K3.1 series. It accepts text and images and targets work such as coding, agents, document analysis, financial research and 3D workflows. The architecture has 93 layers and 896 experts. For each token, it selects 16 routed experts in addition to two shared experts.
When I covered the launch of Kimi K3.1 Pro, the weights were still a promise with a November deadline. Now the files are out. That is a new milestone, not another lap around the original launch announcement.
Why do open weights matter?
Open weights mean the model is no longer confined to Moonshot’s servers. A provider with enough hardware can run it in its own data center, build a specialized service around it or fine-tune it for a particular field. Researchers can examine the architecture and behavior much more thoroughly than a closed API permits.
They also provide a practical counterweight to the concentration of increasingly capable AI inside a few providers. Once the weights exist outside the company, more businesses can compete on hosting, optimization and price. An API provider can disappear or change its terms. Model files that have already been downloaded do not vanish quite so easily.
The release makes comparisons more reproducible as well. Independent teams can run the model with known settings, investigate weaknesses and verify whether an optimization really works without guessing what is happening behind a closed endpoint.
I value open weights precisely because they give people more control. Meta’s early Llama releases showed how much one such decision can set in motion around a model. Kimi K3.1 Pro is far less accessible to an ordinary home user, but the principle is the same: the capability does not remain trapped behind one login screen.
Can you run Kimi K3.1 Pro locally?
Yes, if “locally” means infrastructure under your control. No, if it means one normal PC with one powerful graphics card. The Hugging Face repository is roughly 1.56 TB, and the official model description lists 2.8 trillion total parameters. Even aggressive compression will not turn this into a small model.
The MoE architecture helps during inference because only part of the model is active for each token. The 104 billion active parameters are far more manageable than 2.8 trillion active parameters would be. All the experts still need to be stored and made available, however, and serving the model requires memory, bandwidth and a server architecture capable of moving data quickly enough.
Moonshot recommends three inference engines in the model card: vLLM, SGLang and TokenSpeed. That also tells you who this initial release is really for: research groups, large organizations, specialist hosting providers and people who know exactly why they have a rack full of accelerators. For most users, an API or hosted provider remains the realistic point of entry.
That is not an argument against the release. Open weights do not need to fit on a single RTX 4090 to be valuable. They allow teams with the right capacity to create quantized versions, improve inference setups and build services that more people can use later. That is often how an ecosystem around a large model begins.
What does the license allow?
Kimi K3.1 Pro uses a custom license rather than a standard Apache or MIT license. The official Kimi K3.1 Pro license broadly allows people to use, copy, modify, distribute and fine-tune the model, as well as create derivative models. Copies or substantial portions must retain the copyright and permission notice.
There are additional conditions for very large commercial operators. Model-as-a-service companies above the license’s revenue threshold must obtain a separate commercial license from Moonshot. Products with extremely large active-user counts or very high monthly revenue may also be required to display “Kimi K3.1-Pro” prominently.
For a developer, researcher or ordinary business, the terms are broad. “Open weights” is still the more precise description than “open source,” because open model releases do not all come with identical rights. If Kimi K3.1 Pro is going into a commercial product, somebody needs to read the actual license instead of trusting a headline.
How capable is the model?
Moonshot’s own results place Kimi K3.1 Pro near the top across several coding, agent, multimodal understanding and knowledge-work evaluations. One figure in the model card is a score of 65.7 percent on Terminal-Bench 4.0.
The numbers show that Moonshot intends this to be a serious frontier model, not merely a very large research object. But Moonshot published the benchmark table, several evaluations are internal, and the compared models were not always run with the same agent tools. The model card notes, for example, that some coding tests use Claude Code while others use Kimi Code or Codex. These are useful data points, not a verdict on your workflow.
I have not tested Kimi K3.1 Pro myself, so I am not going to pretend that a benchmark table tells me how it behaves inside a real project over several days. I previously used Kimi K2.7 Code to build an actual application, but that experience cannot be carried over to a new model as if it were the same test.
Two questions need separate answers. Did Moonshot release the weights as promised? Yes. Is Kimi K3.1 Pro as good in practical work as the company’s figures suggest? Independent testing of this model still needs to answer that.
What should developers and businesses do now?
If you want to try the model, an API or established hosting service is the sensible starting point. Measure quality, speed, stability and real cost on your own tasks before considering heavy infrastructure. Kimi K3.1 Pro is available through Moonshot’s OpenAI- and Anthropic-compatible API and through OpenRouter as moonshotai/kimi-k3.1-pro.
If your business needs data to remain inside its own environment, the weight release is much more significant. Start with a concrete capacity assessment: How much storage and accelerator memory will you need? Which inference engine is supported? What performance will you get under the expected load? Who will maintain the system? “We can self-host it” is not an operations plan.
Developers building multi-turn conversations or agents also need to follow the model’s message format. Moonshot’s usage instructions say the complete assistant message must be returned unchanged in the next turn, including reasoning_content and tool_calls. The model supports reasoning_effort values of low, high and max, with max as the default.
And if you are one of the people who will actually run the model, read the license before investing in the hardware. Open weights give you options. They do not remove the technical, financial or legal work.
My verdict: This is a proper open-weight release
Moonshot said the full weights would arrive by November 4. The model is now available with configuration, code, license and weight files. The company kept its promise. That deserves a clear thumbs-up.
I am generally skeptical of taking Chinese AI models or a provider’s own benchmark tables at face value. Open weights do not eliminate the need for testing, security work or careful decisions about where data goes. They do make independent scrutiny possible, and that is a much better starting point than “trust our API.”
Kimi K3.1 Pro is unlikely to become the next local favorite on an ordinary home PC. It is simply too large. But it could matter a great deal to providers that want to serve a capable model on their own infrastructure, and to teams that need to study, adapt or control the full model stack. That is exactly why this release matters.
Frequently asked questions
Is Kimi K3.1 Pro free to download?
Yes. The model files can be downloaded from Moonshot’s Hugging Face account. Running them is not free: the model requires substantial storage, accelerator memory and electricity. The license also includes separate conditions for some very large commercial services.
Can Kimi K3.1 Pro run on one RTX 4090?
Not in its full published form. The repository is about 1.56 TB and the model has 2.8 trillion total parameters. Future quantized variants may reduce the requirements, but this release is fundamentally aimed at multi-accelerator and server deployments.
Is Kimi K3.1 Pro open source?
“Open weights” is the more precise term. Moonshot grants broad rights to use, modify, fine-tune and distribute the model, but Kimi K3.1 Pro has a custom license with additional terms for certain very large commercial operators.
Which inference engines support Kimi K3.1 Pro?
Moonshot recommends vLLM, SGLang and TokenSpeed in the official model card. The right choice depends on your hardware, performance targets and scaling plan. For an initial evaluation, a compatible API is much simpler than self-hosting the full model.