Innhold Show
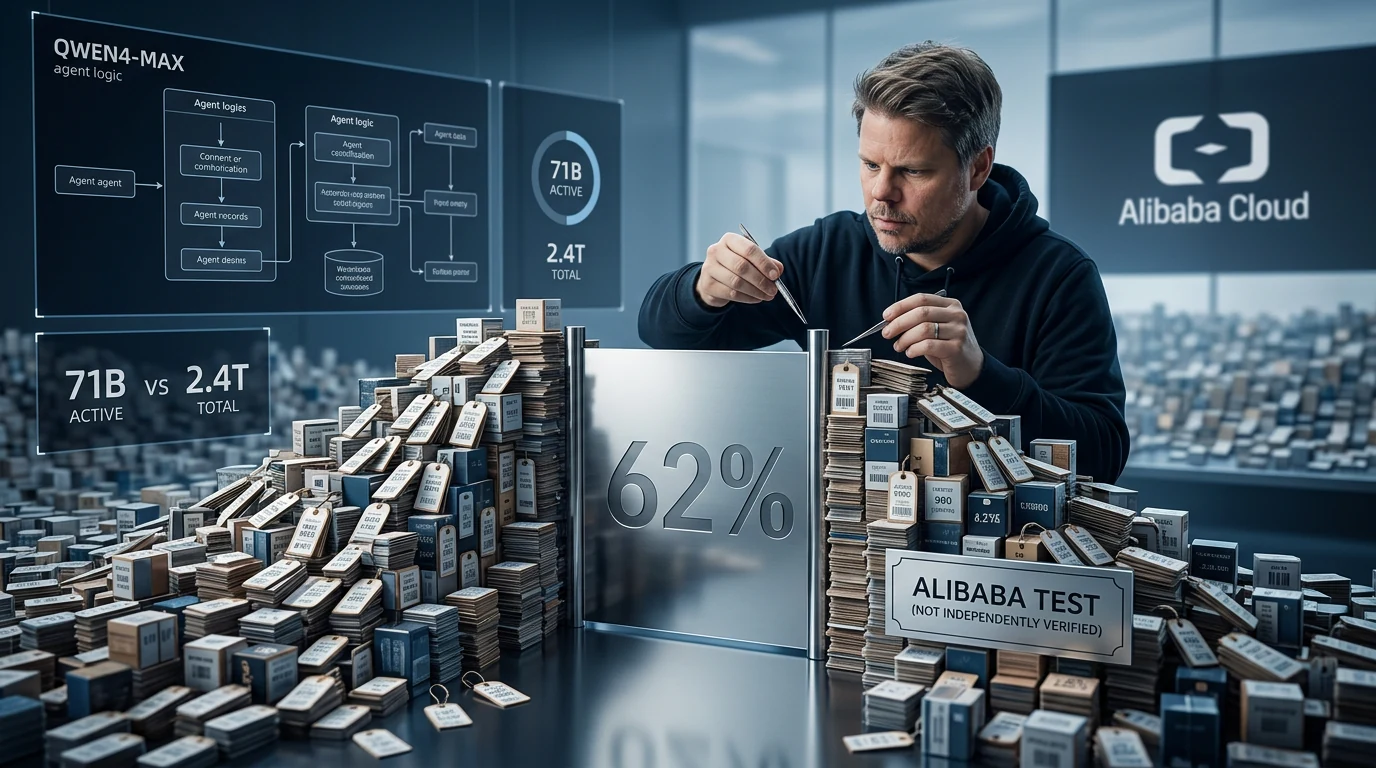
Qwen4-Max pricing could make long AI agent jobs substantially cheaper, but do not read “62% lower cost” as a discount that will automatically appear on your own bill. Alibaba has reduced both token use and API pricing. That is a promising combination for agents that pass large amounts of context back and forth across many steps.
The new flagship model has 2.4 trillion parameters in total, activates 71 billion for each token, accepts text, images and video, and provides a one-million-token context window. Those are enormous numbers, but the practical story is how much useful work the model can complete for the money – not how impressive its model card looks.
I am holding back the applause for now. The cost reduction comes from Alibaba’s own Work360 evaluation, and Qwen4-Max is a proprietary cloud service. I have not tested the model myself. Developers and businesses should not move everything on launch day. They should compare Qwen4-Max with their own tasks, quality requirements and total costs.
What is Qwen4-Max?
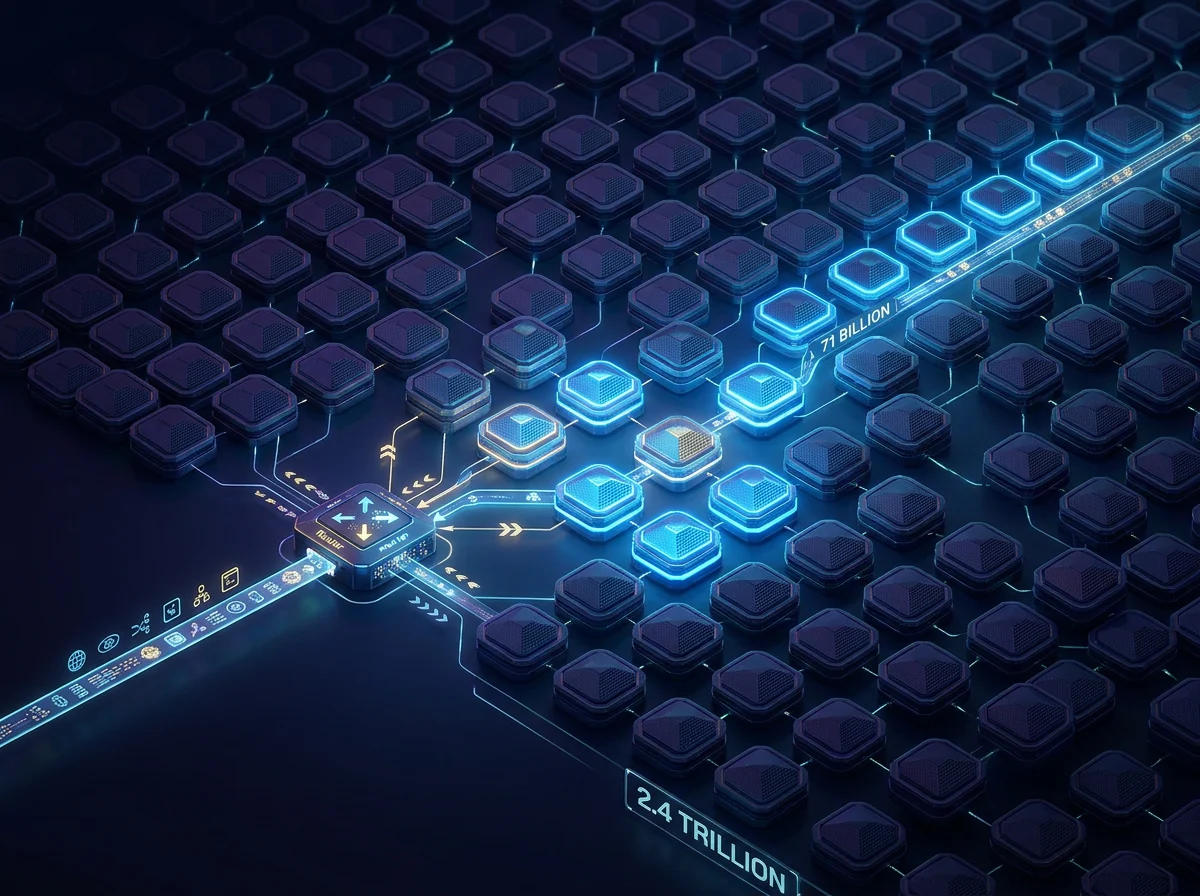
Qwen4-Max is Alibaba’s new proprietary flagship model in the Qwen family. According to Alibaba’s November 16, 2026 announcement, it uses a Mixture-of-Experts architecture with 2.4 trillion parameters in total but only 71 billion active parameters per token. It handles text, images and video within a one-million-token context window.
A Mixture-of-Experts architecture does not run the entire model for every token. It routes work through a selection of experts, allowing Qwen4-Max to offer very large total capacity without activating all 2.4 trillion parameters every time. Alibaba says it activates 25% fewer parameters than Qwen3.8-Max even though the two models have the same total parameter count.
That is more useful than the record-sized total on its own. Fewer active parameters can reduce inference costs, but they do not tell us whether the model is good. Routing, training, memory use, software efficiency and the number of tokens needed to solve a task all matter. A huge model that wanders through a forest of unnecessary text can still be expensive to operate.
Why do 71 billion active parameters matter?
The 71 billion active parameters show how Alibaba is trying to get more capacity from less computation per token. Qwen4-Max has roughly 34 times as many total parameters as it activates for a single pass. That does not make the model small, but it makes “2.4 trillion” far less useful as a measure of the actual cost of an API call.
For anyone building an agent, active parameter count is not the final goal anyway. The agent has to read documents, choose tools, write code, check the result and finish the job without five extra repair rounds. If a cheaper model uses fewer tokens but creates more human cleanup, the cost has merely moved from the API bill to working time.
Alibaba says Qwen4-Max used 35% fewer tokens than Qwen3.8-Max in Work360 at “High” reasoning effort. Its score in the same evaluation increased from 47.74 to 52.69. That is a more meaningful signal than parameter count because it connects resource use with an outcome. Work360 is still Alibaba’s own evaluation across 721 fields, so the numbers do not guarantee the same improvement in your codebase, document workflow or customer service system.
Qwen4-Max pricing: how much does it cost?
Qwen4-Max costs $1.50 per million input tokens and $4.50 per million output tokens on QwenCloud, according to the pricing reported in MarkTechPost’s launch coverage. These are international dollar prices, not conversions from a regional price.
Cached input costs $0.075 per million tokens. Alibaba confirms the cache rate and says the model is available through the QwenCloud Token Plan and API, as well as QwenWork and QwenStudio. MarkTechPost also lists OpenRouter as an access route. For a long agent job, caching can matter as much as the standard input price because the same instructions, files and previous tool results are often sent again over many rounds.
A simple example makes the pricing easier to judge. A request with 100,000 uncached input tokens and 20,000 output tokens costs about $0.24 before tool calls, additional rounds or other charges. If most of the repeated input hits the cache, that part of the bill drops sharply.
This does not mean you should fill the one-million-token context just because the space exists. Long contexts cost money, can make relevant details harder to find and may be transmitted repeatedly during an agent run. Good context management is still better than dumping an entire file server into the model and hoping for the best. One million tokens is capacity, not an instruction.
What does the 62% cost reduction mean?
Alibaba measured an average Work360 cost of $1.67 per task with Qwen4-Max, compared with $4.43 for Qwen3.8-Max. That is a 62% reduction. The Work360 score increased at the same time, so the new model was both better and cheaper on Alibaba’s own tasks.
The saving comes from two places: a lower price per token and fewer tokens used. It does not mean every API rate was cut by 62%. It also does not mean every customer workflow will become 62% cheaper. Task mix, reasoning effort, cache hits, tool calls, retries and response length can change the result considerably.
This is a classic case of a vendor claim that can be mathematically correct and still easy to misunderstand. The move from $4.43 to $1.67 checks out. But Work360 was created and run by Alibaba, and the available source material contains no independent reproduction of this particular cost test. I would use 62% as a good reason to evaluate Qwen4-Max, not as a finished budget figure.
What can one million tokens and native vision do?
A one-million-token context window makes Qwen4-Max relevant for large document collections, long codebases and agent runs that need substantial history available at once. Native vision lets the same model interpret text, diagrams, screenshots and other visual input without a separate vision model. That can simplify systems working across documents and interfaces.
Alibaba highlights coding, office tasks, visual reasoning, 3D modeling, game development and industrial work. In one demonstration, the company says the model reduced manual programming time for a machining task from about 475 minutes to 24. Alibaba also describes a 48-hour agent run for coolant research and another experiment involving 454 tool calls and 3,239 measurements while developing molecular candidates.
These examples reveal how Alibaba wants Qwen4-Max to be used: as an engine for long, tool-using workflows, not merely a chatbot with a very large memory. They are still vendor demonstrations. They show that the system was designed for this type of work, but they do not prove that it can run without oversight in machining, research or other fields where mistakes become expensive.
Is Qwen4-Max an open model?
No. Qwen4-Max is offered as a proprietary service through Alibaba’s platforms and API. Alibaba says smaller Qwen4 models with open weights will follow, but that promise does not make the Max model open today. You can use the service, but you cannot download its weights for local deployment or inspect the full model.
The distinction matters because the Qwen name is often associated with models that can be downloaded and run independently. Qwen4-Max is a different product choice. Businesses need to assess pricing, availability, data handling and vendor lock-in as they would with any other cloud service.
I am skeptical of Chinese models, but I have no interest in rejecting them by reflex. Qwen models have repeatedly been technically strong and aggressive on price. That is exactly why the assessment should be concrete: What data leaves your systems? Where is it processed? Which agreements apply? Is the quality good enough on the actual jobs? Nationality does not replace that review, and a pretty benchmark does not replace it either.
Should you use Qwen4-Max for AI agents?
Qwen4-Max is worth a limited pilot if you have long, expensive agent runs where context, caching and many tool steps dominate the bill. The prices are low enough to make it interesting as an option in a model router, particularly for document-heavy tasks and workflows with a great deal of repeated input.
Do not start with the parameter count or the tallest bar on a benchmark chart. Select a small set of representative tasks, define the quality criteria in advance and measure the complete run: completion rate, token use, retries, tool errors, latency and the amount of human correction still required. Compare cost per approved result, not cost per first response.
Keep sensitive production data out of the system until data processing, storage and contractual terms are clear. That advice applies to every external model API, but a proprietary service gives you less control than open weights running on your own infrastructure.
Qwen4-Max looks like a serious pricing attack on the agent-model market. One million tokens, native vision, fewer active parameters and extremely cheap cached input could make a practical difference. But the test that matters begins when Alibaba’s tasks are replaced with yours. Measure before you move. It is less exciting than “62% cheaper,” but far more useful.
Frequently asked questions
Can Qwen4-Max run locally?
No. Qwen4-Max is a proprietary model offered through QwenCloud and other Alibaba services. Alibaba has announced smaller Qwen4 models with open weights, but that does not mean the Max model’s weights will become available for local deployment.
How much does one million tokens cost with Qwen4-Max?
QwenCloud charges $1.50 for one million input tokens and $4.50 for one million output tokens. Cached input costs $0.075 per million tokens. Tool calls, retries and additional model rounds can increase the total cost of an agent job.
Will every AI agent task become 62% cheaper?
No. The 62% figure is the reduction Alibaba measured in its own Work360 evaluation, from $4.43 to $1.67 per task. Your saving depends on token use, cache hits, tool calls, retries, quality and the amount of human correction required.
How large is the Qwen4-Max context window?
Qwen4-Max has a one-million-token context window. That creates room for large document sets, long codebases and extensive agent history, but filling the window without a reason can increase cost and make irrelevant information harder for the model to ignore.