
Innhold Show
If you were hoping to open Gemini 4 Carbon today and turn it loose on your own code, you will have to wait. Google’s new frontier model is initially available only to a small group of cyber defenders. What makes Carbon worth watching is that it tackles something far more useful than slightly better chatbot answers.
Carbon is built for long-running agent workflows and the full cyber defense chain: finding a vulnerability, determining whether it can actually be exploited and producing a working fix. Google announced the model on October 28, 2026, only two weeks after Gemini 4 Argon.
My assessment is cautiously positive. The results look strong, and limited access makes sense when the same capabilities can be used for both defense and attack. But Google is mainly presenting its own measurements, selected evaluations and experience from its internal teams. This is promising evidence, not an invitation to treat Carbon as a production-ready security teammate.
What is Gemini 4 Carbon?
Gemini 4 Carbon is Google’s newest frontier model for demanding coding, long-running agent tasks and cybersecurity. It builds on Gemini 4 Argon, released on October 13, 2026, but Carbon has a much clearer role as a working tool for cyber defenders.
Google says its internal teams have let Carbon work for several days on complicated assignments. These include tracing the root cause of subtle bugs in large codebases, navigating dead ends and patching low-level systems. That persistence is the interesting part. A security agent that gives up after the first failed tool call is not much of an agent.
Carbon is also a general-purpose model. Google highlights improvements in full-stack development, multimodal understanding, scientific tasks and ordinary agent work. Even so, cybersecurity is the clear reason this model has its own launch, and it explains why the rollout begins so cautiously.
What makes Carbon different in cyber defense?
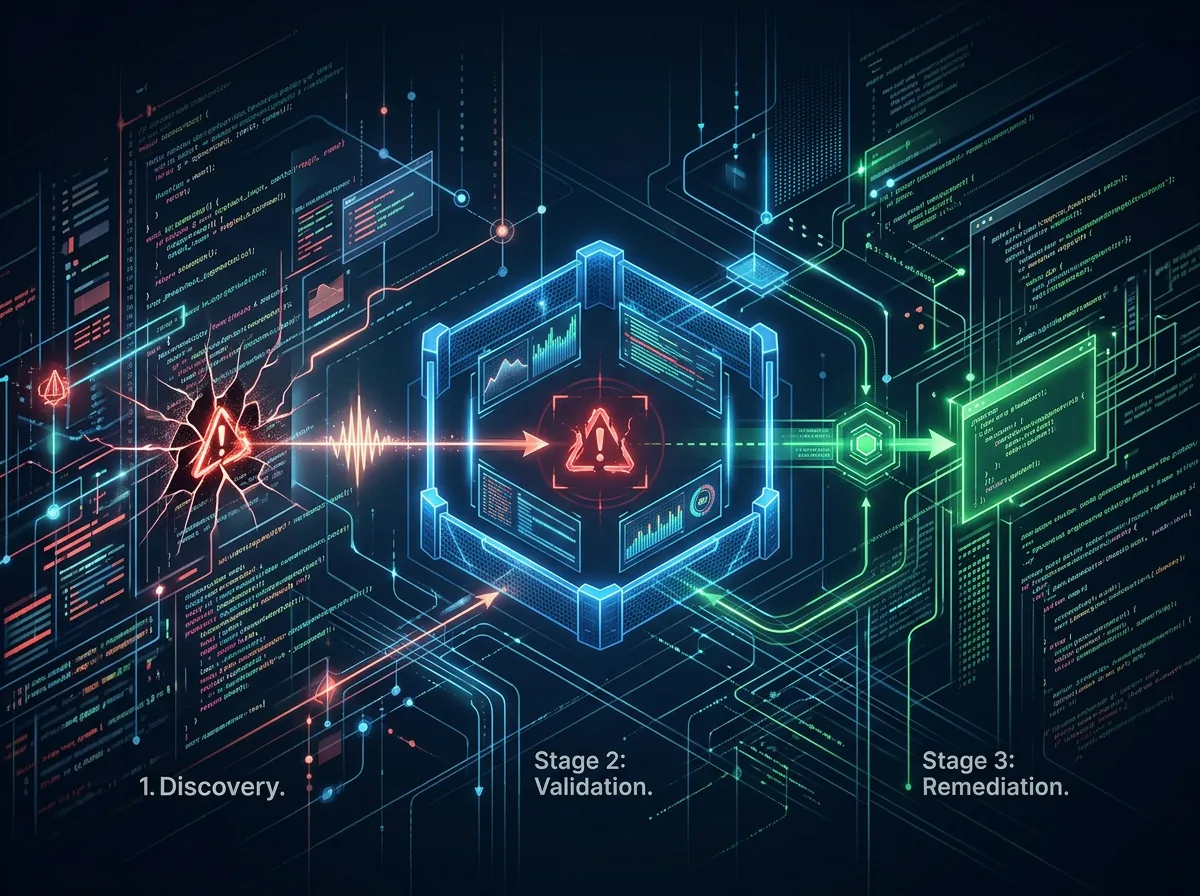
The important difference is that Carbon goes beyond vulnerability scanning. The model is intended to find real flaws in code, prove whether they can be exploited and then fix the root cause. Those are three different jobs. A long list of possible vulnerabilities has little value if nobody can separate dangerous findings from noise or get a safe patch into production.
Google reports 88.2 percent on SEC-bench Pro for finding vulnerabilities, 54.8 percent on ExploitGym for validating them through exploitation and 71.0 percent on CWE-bench for producing patches. These external benchmarks were run without the guardrails included with the deployed model. The numbers therefore describe raw capability, not exactly what an ordinary user will be allowed to access.
Google also says Carbon more than doubled the success rate for generating secure code compared with Argon in internal testing. The Chrome team reportedly achieved more than ten times better results on high-quality patches than with an unnamed frontier model from another lab. That sounds impressive, but without the competitor’s name, the full test setup and the methodology, it remains a vendor claim.
The direction still matters more than any single score. Cyber defense has long been full of tools that find more issues than people have time to process. A model that can prioritize, validate and repair could shorten the path from finding a flaw to actually protecting a system. If it works as well on messy business code as it does in the evaluations, that would be a real leap.
How much should you trust the results?
Not enough to buy champagne based on a leaderboard. Artificial Analysis ranks Carbon first on its Intelligence Index v5 with 59 points, but it also makes clear that the model does not lead in every area. Claude Opus 5.5 still ranks ahead on the company’s Coding Agent Index.
That is a useful correction to the headline that Carbon is number one. A composite index mixes several kinds of work into one score. It says little about how well the model will handle your codebase, internal tools, poor logs, incomplete requirements and a CI pipeline that prefers Friday afternoon for its nervous breakdowns.
The strongest part of the evidence is not the position on a general leaderboard. It is the attempt to solve a complete operational chain, backed by external cybersecurity evaluations covering three distinct stages. What is missing matters just as much: at launch there is no public Carbon model page in the Gemini API documentation, no broad access and no public experience from ordinary development teams.
Why is access to Carbon limited?
Carbon is rolling out first to a subset of cyber defenders through Google’s Fairwind program. Google says the model is also going through a voluntary US government process for pre-release testing. More trusted partners will receive access gradually, while developers, businesses and consumers must wait.
The logic is to give defenders a head start before strong offensive capabilities become widely available. Carbon does not merely identify a vulnerability. It also scored 54.8 percent on an evaluation where the job is to exploit one. With that kind of dual-use capability, a staged opening is more than the usual scarcity around a new model.
Limited access also means that most of Google’s claims are difficult to verify in ordinary work. It is not yet clear how Carbon behaves with organization-specific rules, enormous monorepos, unfinished integrations or security tools that return contradictory findings. A closed preview can produce good answers to those questions, but those answers are not public yet.
Has Google solved agent failure?
No, but the company says it has reduced several of the most frustrating failure modes. In Google’s internal testing, high-severity alerts for misaligned behavior fell by almost 80 percent compared with Argon. The model also reportedly cut unsupported claims roughly in half, reduced overreach by 26 percent and reduced under-service by 29 percent.
Google also reports a 0.0 percent success rate for indirect prompt injection attacks in Gray Swan’s evaluation, compared with 0.7 percent for Argon. That is a good result in that particular test. It does not mean prompt injection has been solved. Zero successful attacks in one evaluation is not the same thing as zero risk when the model encounters new websites, documents, tools and attackers.
I still like that Google is measuring more than whether the model completes a task. An agent can be technically capable and still be terrible to trust with responsibility. It can guess when evidence is missing, hide a failed tool call or continue far beyond the assignment. Carbon is supposed to surface conflicting sources, explain what is missing and stop when an action is blocked. Those qualities matter in real agent work.
How much will Gemini 4 Carbon cost?
Google lists an introductory price of $2 per million input tokens and $10 per million output tokens. Cached input will receive a 95 percent discount. These are international API prices published by Google, but they do not make Carbon publicly purchasable at launch.
After the introductory period, the price rises to $4 per million input tokens and $20 per million output tokens. Google has not given a specific end date for the Carbon discount. Because the model is not yet publicly available in the Gemini API, these prices describe the planned broader access rather than something an ordinary developer can buy today.
The token price also says little about the real cost of a long-running cyber agent. If Carbon works for several days, reads large codebases, uses tools and produces many intermediate results, total consumption can become substantial. When access arrives, measure cost per validated finding or approved patch. Price per million tokens is the spreadsheet. Completed work is reality.
What should developers and businesses do now?
Ordinary developers do not need to change anything today. There is no public model ID to migrate to, and Google has not provided a date for broad access. Watch the official Gemini API documentation, pricing terms and any model card before planning Carbon into production.
Security teams can use the waiting period more productively. Identify workflows where an agent could deliver measurable value without receiving free rein: prioritizing scanner findings, reproducing issues in isolated environments, proposing patches and verifying them through tests. Require traceability, human approval and firm limits on which systems and secrets the agent can reach.
When Carbon becomes available, measure it against the current process rather than against a blank chatbot. How many real vulnerabilities does it find? How many false alarms does it create? Do the patches pass the tests, and do they introduce new flaws? How often does a person have to clean up? Those answers will decide whether Carbon is a leap or merely a very attractive chart.
My assessment of Gemini 4 Carbon
Gemini 4 Carbon looks like one of the more focused frontier-model launches this year. Google has not simply added a higher model number and displayed a general score. Carbon targets a concrete problem: moving an agent from vulnerability discovery to validated risk and then to a working fix.
That could be extremely useful. It could also be dangerous if the same capabilities reach the wrong hands, or if businesses connect the model to critical systems before the controls are good enough. The limited rollout is therefore part of the product as it exists today, not a footnote.
I do not accept “number one” as a final verdict. I do accept that Google has shown enough concrete results for Carbon to deserve attention. The real test begins when independent developers and security teams can use it on messy, living systems, complete with all the boring details a benchmark never has to face.
Frequently asked questions
Is Gemini 4 Carbon publicly available?
No. At launch, Google is giving access to a subset of cyber defenders through the Fairwind program. The company says Carbon will later reach developers, businesses and consumers, but it has not announced a date for broad availability.
Can I use Gemini 4 Carbon through the Gemini API?
Not through a public model ID as of its October 28, 2026 launch. Google has published planned API prices, but Carbon is not yet broadly available. Wait for official API documentation and a model listing before planning an integration or migration.
Is Gemini 4 Carbon better than Claude Opus 5.5 and GPT-6 Astra?
Carbon leads the Artificial Analysis Intelligence Index v5 overall, but it does not lead every category. Claude Opus 5.5 ranks ahead on the Coding Agent Index. The best model depends on the job, and Carbon’s cyber results still need confirmation in ordinary production environments.
Is Gemini 4 Carbon an offensive hacking model?
Google presents Carbon as a cyber defense model, but it can also validate vulnerabilities through exploitation in controlled evaluations. That dual-use capacity is precisely why access begins with selected defenders, guardrails and a gradual rollout rather than immediate public availability.